CUBE F0 Estimator
An open-source, noise-robust pitch tracker for speech, singing voice and instrumental music. The smallest model has 1.84M parameters and runs about 50 times faster than real time on one CPU thread.
CUBE (Consensus U-Net Branchformer Estimator) estimates the fundamental frequency (F0) every 10 ms, together with a voiced/unvoiced decision. It is built to keep working when the audio is not clean: its accuracy holds up under white, pink, babble, ambient and music noise, and under reverberation.
It comes in four sizes. CUBE-L is the most accurate; CUBE-M, CUBE-S and CUBE-T are distilled from it, and CUBE-T is small enough for CPU and real-time use.
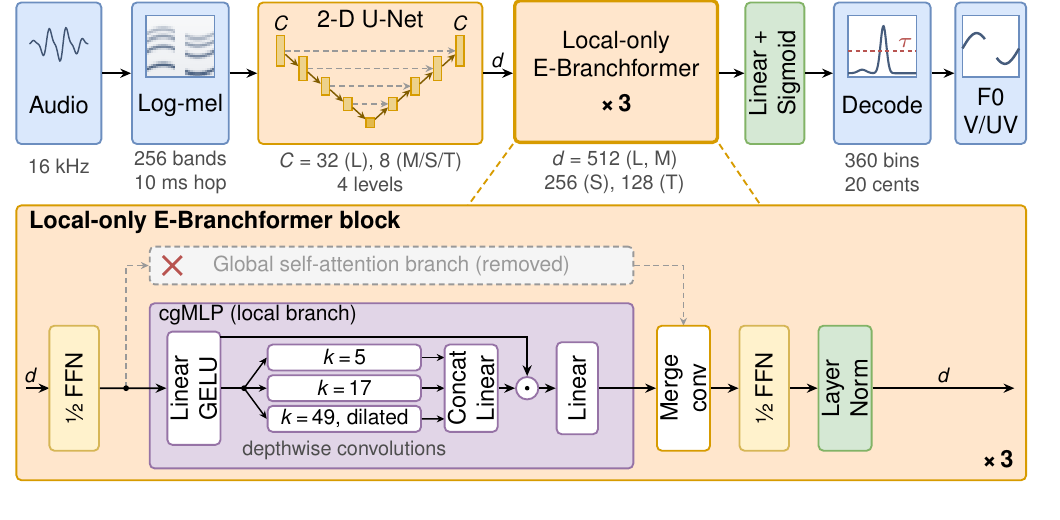
How it works
- The 16 kHz waveform becomes a 256-band log-mel spectrogram with a 10 ms hop.
- A four-level 2-D U-Net processes the spectrogram and projects every frame to a vector.
- Three local-only E-Branchformer blocks model time. Global self-attention is removed, so only local context is used.
- A sigmoid layer scores 360 pitch bins, 20 cents apart, from 31.7 Hz to 2005.5 Hz. A frame is voiced when its peak score passes a threshold, and F0 is the score-weighted average around the peak.
Consensus labels. Training data is augmented with speech and singing resynthesized from F0 contours that several DSP pitch trackers agree on. No neural F0 estimator is used to make the training labels.
Results
Raw pitch accuracy (RPA, share of voiced frames within 50 cents) and voicing F1, in percent, averaged over six test corpora. Noisy averages seven conditions: six additive noise types from 20 to −10 dB SNR, plus measured reverberation.
| Model | Params (M) | GMACs | RPA clean | RPA noisy | F1 clean | F1 noisy | RTF, CPU 1 thread |
|---|---|---|---|---|---|---|---|
| CUBE-L | 27.80 | 19.31 | 94.88 | 84.39 | 94.52 | 87.23 | 0.203 |
| CUBE-M | 22.19 | 5.31 | 94.69 | 83.94 | 94.36 | 87.24 | 0.055 |
| CUBE-S | 6.06 | 2.09 | 94.67 | 83.69 | 94.37 | 86.95 | 0.027 |
| CUBE-T | 1.84 | 1.25 | 94.65 | 83.03 | 94.39 | 86.83 | 0.019 |
| RMVPE | 90.40 | 7.67 | 94.30 | 80.58 | 93.89 | 84.50 | 0.080 |
| FCPE | 10.83 | 2.14 | 95.00 | 78.21 | 93.18 | 81.93 | 0.025 |
GMACs are for 2 s of audio. RTF is processing time divided by audio duration (lower is better), measured on a 10 s clip with batch size 1 in fp32. Every CUBE model beats RMVPE and FCPE in noise; CUBE-T does it with the lowest CPU cost of all six.
Try it
git clone https://github.com/errayeren/robustf0estimation.git
cd robustf0estimation && pip install .
cube-f0 input.wav --model cube-t --out f0.csv
import cube

model = cube.CUBE.from_pretrained("cube-t")   # or cube-l, cube-m, cube-s
y, sr = cube.load_audio("example.wav")
out = model.predict(y, sr)   # time_s, f0_hz, confidence, voiced
The code is MIT-licensed. The pretrained weights are CC BY-NC-SA 4.0 (non-commercial), because some training data is licensed for non-commercial use only. Training code and the consensus-labelling pipeline will be released when the paper is accepted.